


Before you start
You need:- A pipeline you have built and checked, ready to deploy. If you have not run one yet, work through the first labeled dataset tutorial first.
- Your items in a dataset. The pipeline’s Start node decides which of them a run picks up — its dataset choice, its filter, and its Max items to launch field.
- A funded team balance. Billing is pay-as-you-go for the items a run actually processes, and a run cannot deploy on an empty balance.
Step 1 — Keep each run within the per-run limit
Decide which items the run will label. On the Start node, choose the dataset, and use the filter and the Max items to launch field so the run picks up no more than 10,000 items. You can instead ask the agent to set the dataset, filter, and maximum together in one change. The node counts its matching items as soon as a dataset is chosen; with a maximum set, the line also shows how many will launch: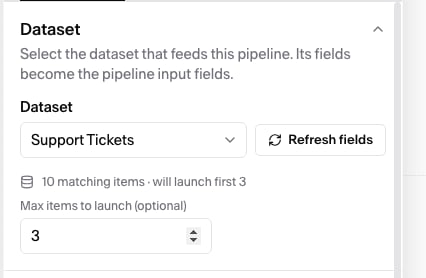
Step 2 — Deploy the first batch
Open the Pipeline tab and click Deploy in the bottom toolbar. The Cost breakdown (forecast) window opens with the cost for this run.If the pipeline’s checks have not been run, an Issues window appears first. Unrun test checks are warnings you can override with I want to deploy with unresolved warnings; the built-in lints must finish before deployment. These are Quality Requirements and User Interface Types on labeling nodes, Dataset Items on Start, and Exam Golden Dataset on expert-labeling nodes with an enabled exam. Lints start automatically after saved edits; use Run lints to retry a failed lint. Failed checks block deployment. See Self-check. Clear the window and the cost window follows.
- Review the run’s Expected and Maximum totals.
- Tick the consent checkbox. It confirms that the per-item price is fixed at deploy, that the totals are estimates billed pay-as-you-go for the items the pipeline actually processes, and that the configuration cannot change after launch.
- Click Confirm and deploy.
Step 3 — Clone the pipeline for the next batch
Deployment locks a pipeline against edits and reruns. If deployment failed, fix and redeploy the same pipeline. Otherwise, open Pipeline → More pipeline actions in the bottom toolbar and click Clone. The copy keeps the name and takes the next version number, which appears in export filenames. You can also clone through the public API. The agent cannot clone the pipeline. A new pipeline opens in the same project with the same configuration. The original stays locked and untouched. The copy has no run yet, so its nodes are editable and its Deploy button is active again.Step 4 — Point the copy at the next batch
A clone starts out reading the same dataset as its source, so re-point it at the next batch before you deploy. The platform writes each run’s output fields back to the dataset, stamped with the run that produced them, so a filter can select only the items an earlier run has not labeled yet. Skip items an earlier run already labeled. After the first run finishes, tick the copy’s filter checkbox No revision for this field on the field the pipeline writes its result to, either by hand on the Start node or by asking the agent. The next run then launches only the items where that field is still empty. This works when all of these hold:- the pipeline has deployed at least once. The output field is created at the first deploy, so it exists for the filter to test.
- the previous run finishes before the next one deploys. The filter reads only values recorded before launch, so an in-flight run’s items are re-selected and charged again.
- the output field’s name stays unchanged across clones. A renamed field is a new dataset field, so every item looks unlabeled again. If a field with the same name has a changed shape, the deploy fails with a schema-mismatch error.
- any recorded value counts as done. Another pipeline writing the same field, or the agent importing values into it, also excludes an item. A failed item, which wrote no value, is picked up again.
- Tag each item with a batch value in your data. For example, use a
batchfield set to1,2,3. On the copy’s Start node, use the column filter to keep one batch value per run. The filter matches a field’s value exactly, so a batch tag selects that batch cleanly. - Split the data into separate files. Upload each batch as its own dataset (for example, one 10,000-item file per batch) and point each run’s Start node at the next one.
Step 5 — Deploy the copy, and repeat
Deploy the copy the same way as in Step 2. It gets its own cost window and frozen contract, priced fresh, since a clone does not inherit the first run’s prices (see Pipeline pricing). The copy’s run starts and its Items tab fills with the new batch, while the first pipeline’s finished run stays untouched. Repeat once per batch.Costs and funding
The Cost breakdown (forecast) window computes everything for the current run. The two labeling paths bill differently. Expert labeling charges the per-task price you set plus the platform commission for each expert per item, with review and one-time onboarding and exam charges added separately. Synthetic labeling charges generation tokens plus LLM review. Pipeline pricing covers every cost line, what Expected and Maximum mean, and the contract that freezes prices at deploy. Billing covers how the team balance is drawn down. For this batch workflow:- Size a month. Divide the Total row’s Expected figure by the run’s item count for a per-item figure, then multiply by your monthly volume.
- Fund before you deploy. Fund to at least the run’s Maximum total. The deploy window flags a shortfall, but the platform blocks deploying only on an empty balance (below $0.01). A shortfall can pause the run midway, though it does not block the deploy. See Billing.
- Resume after a pause. If the balance runs out mid-run, the run pauses. Top up, then resume. Resume or cancel a pipeline run covers the controls.
What this does not do
- There is no setting that raises the 10,000-items-per-run limit. Anything above it requires more runs.
- Runs do not chain automatically. Each run’s batch is whatever its Start node selects at that moment. The platform does not queue the next batch on its own. To skip items an earlier run labeled, set the filter described in Step 4 yourself.
- A large standing volume is many cycles. Hundreds of thousands of items a month is dozens of clone-and-deploy cycles. In the UI each carries its own cost window and consent; over the public API, where deploying, cloning, and canceling are available, you can script the cycle instead of running it by hand.
Related
- Pipeline pricing — the cost lines, Expected vs Maximum, and the contract freeze
- Billing — team balance, charges, and automatic pauses
- Start and End nodes — the full filter and item-limit rules behind Steps 1 and 4
- Export your labeled results — collecting each batch’s results, and merging exports across batches